 Active
DiaryBench
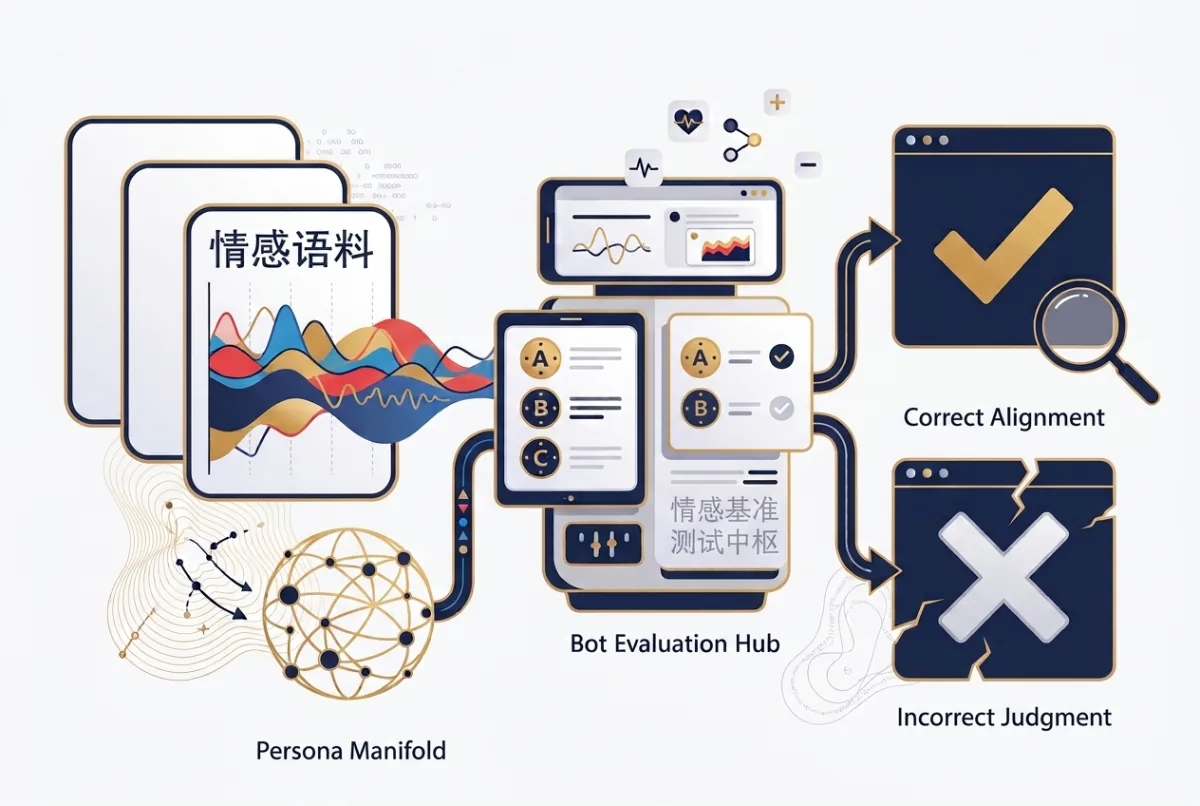
A private-diary benchmark for fine-grained emotional reasoning across long sequences.
- TYPE
- emotional reasoning / benchmark
- STATUS
- active / private source
- QUESTION
- Can a model distinguish emotional evidence from over-reading?
- SOURCE
- my private Chinese diary · author-verified
- UPDATED
- September 28, 2026
| # | MODEL | SCORE |
|---|---|---|
| 1 | GPT-6 Astra | 64.83 |
| 2 | GPT-6 Sol EH | 63.06 |
| 3 | Grok 4.6 | 55.10 |
| 4 | GLM-5.3 | 54.28 |
| 5 | Claude Opus 5 | 53.83 |
Aggregate scores only; the diary and answer key remain private.